Synthetic Pretraining Data For Large Language Models (LLMs) Market Size And Forecast 2026–2030: Trends Driving Industry Expansion
Backed by market attractiveness analysis, total addressable market sizing, company benchmarking matrices, interactive Excel dashboards, wider supply chain intelligence, emerging startup coverage, and detailed product-level insights, The Business Research Company’s 2026 market reports are designed to offer research that is more actionable and strategically valuable than ever.
Synthetic Pretraining Data For Large Language Models (LLMs) Market Size Outlook: How Quickly Will Revenue Expand Through 2030?
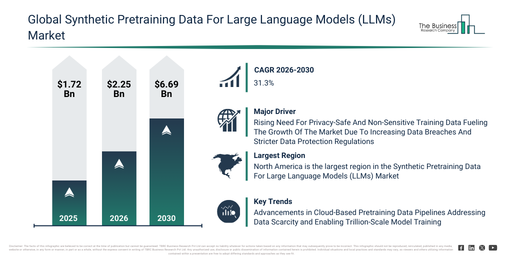
The market for synthetic pretraining data for large language models (LLMs) has experienced significant expansion in recent years. This market is expected to increase from $1.72 billion in 2025 to $2.25 billion in 2026, achieving a compound annual growth rate (CAGR) of 31.1%. Historically, this growth can be attributed to several factors including the limited availability of labeled text data, strict data privacy restrictions, past shortages of NLP datasets, the increasing need for training large models, and the rising costs associated with data licensing.
The market for synthetic pretraining data for large language models (LLMs) is anticipated to experience substantial exponential growth in the coming years. It is forecast to reach $6.69 billion in 2030, demonstrating a robust compound annual growth rate (CAGR) of 31.3%. This expansion during the projected period is driven by factors such as the increasing development of foundation models, a rising necessity for safe training datasets, growing demand for multilingual models, heightened regulatory data compliance requirements, and the proliferation of domain-tuned LLMs. Key developments expected within this forecast period include the emergence of domain-specific synthetic text corpora, techniques for generating privacy-safe training data, platforms for multilingual synthetic datasets, sophisticated pipelines for bias-controlled synthetic data, and frameworks for automated data augmentation.
Get A Free Sample Report With In-Depth Market Insights:
Synthetic Pretraining Data For Large Language Models (LLMs) Market Industry Drivers: What’s Behind The Revenue Growth?
The increasing necessity for privacy-secure and non-sensitive training data is anticipated to fuel the expansion of the synthetic pretraining data market for large language models (LLMs). This requirement for privacy-safe and non-sensitive training data reflects the intensifying pressure on organizations to protect personal and confidential information, such as health records, financial data, and personally identifiable information, during AI model training and fine-tuning procedures. The demand for privacy-safe training data is on the rise as organizations respond to an increasing number of data breaches and more stringent data protection regulations, which restrict the use of real-world sensitive datasets in AI development. Synthetic pretraining data addresses these challenges by replacing actual personal or proprietary information with artificially generated datasets that retain relevant statistical and semantic characteristics without containing identifiable or sensitive content. For instance, in September 2025, Perforce Software, Inc., a U.S.-based software development company, disclosed that approximately 60% of organizations experienced data breaches or data theft across software development, AI, and analytics environments, representing an 11% year-over-year increase. This trend highlights the escalating risks associated with utilizing real-world data for AI training and reinforces the need for privacy-preserving alternatives. Therefore, the growing need for privacy-safe and non-sensitive training data is propelling the growth of the synthetic pretraining data for large language models (LLMs) market.
Synthetic Pretraining Data For Large Language Models (LLMs) Market Segment Outlook: Which Categories Are Growing Fastest?
The synthetic pretraining data for large language models (llms) market covered in this report is segmented –
1) By Data Type: Text; Code; Multimodal; Domain-Specific; Other Data Types
2) By Source: Proprietary; Open Source; Third-Party
3) By Deployment Mode: Cloud; On-Premises
4) By Application: Model Training; Model Evaluation; Data Augmentation; Other Applications
5) By End-User: Technology Companies; Research Institutes; Enterprises; Other End-Users
Subsegments:
1) By Text: Natural Language Documents; Conversational Text Data; Structured Text Records; Unstructured Text Content
2) By Code: Programming Language Scripts; Software Development Instructions; Algorithmic Logic Code; Source Code Repositories
3) By Multimodal: Text And Image Data; Text And Audio Data; Text And Video Data; Integrated Multiformat Content
4) By Domain-Specific: Healthcare Industry Data; Financial Services Data; Legal And Regulatory Data; Manufacturing And Industrial Data
5) By Other Data Types: Tabular Data Records; Log And Event Data; Simulated Scenario Data; Annotated Metadata Content
#Synthetic Pretraining Data For Large Language Models (LLMs) Market Growth Trends: What’s Shaping The Future Outlook?
Major companies in the synthetic pretraining data for large language models (LLMs) market are concentrating on advancements in cloud-based pretraining data pipelines. These pipelines merge synthetic data generation with extensive data curation and quality-conscious optimization to tackle data scarcity, enhance model performance, and enable the training of trillion-parameter models. Cloud-based synthetic pretraining data pipelines combine artificially produced high-quality datasets with carefully selected proprietary and domain-specific data, improving the efficiency and effectiveness of LLM pretraining beyond conventional web-scale sources. For instance, in August 2025, DatologyAI, a US-based venture-backed AI startup, launched BeyondWeb, an advanced platform for data curation and training optimization designed to extend large language model training beyond traditional web datasets. BeyondWeb prioritizes large-scale synthetic data integration, automated data valuation, and quality-aware filtering to identify and give precedence to high-value training data. These features allow for better model generalization, increased robustness, and improved training efficiency at extreme scales, supporting trillion-parameter model pretraining without a proportional increase in computational cost.
Synthetic Pretraining Data For Large Language Models (LLMs) Market Competitive Overview And Top Companies
Major companies operating in the synthetic pretraining data for large language models (llms) market are Amazon Web Services Inc., NVIDIA Corporation, IBM Research, Microsoft Research, OpenAI Inc., Databricks Inc., Anthropic PBC, Cohere Inc., Innodata Inc., AI21 Labs Ltd., Hugging Face Inc., Snorkel AI Inc., Gretel Labs Inc., Meta Platforms Inc., Aleph Alpha GmbH, Bitext Innovations S.L., SuperAnnotate AI Inc., Google LLC, Syntheticus Inc., MOSTLY AI Solutions MP GmbH, YData LDA, Diveplane Corporation
View The Full Synthetic Pretraining Data For Large Language Models (LLMs) Market Report:
Synthetic Pretraining Data For Large Language Models (LLMs) Market Top Region: Where Does Most Revenue Come From?
North America was the largest region in the synthetic pretraining data for large language models (LLMs) market in 2025. Asia-Pacific is expected to be the fastest-growing region in the forecast period. The regions covered in the synthetic pretraining data for large language models (llms) market report are Asia-Pacific, South East Asia, Western Europe, Eastern Europe, North America, South America, Middle East, Africa.
Reach Out To Our Team:
The Business Research Company: https://www.thebusinessresearchcompany.com/
Americas: +1 310-496-7795
Asia: +44 7882 955267 & +91 8897263534
Europe: +44 7882 955267
Email us at: marketing@tbrc.info
Follow us on:
LinkedIn: https://in.linkedin.com/company/the-business-research-company
YouTube: https://www.youtube.com/channel/UC24_fI0rV8cR5DxlCpgmyFQ
Global Market Model: https://www.thebusinessresearchcompany.com/global-market-model